Case study · multi-agent systems, AI security
Attacking my own AI, safely
A multi-agent platform that continuously red-teams the clinical co-pilot as a black-box attacker: it reaches the deployed app over HTTP only, with no access to its code, database or logs.
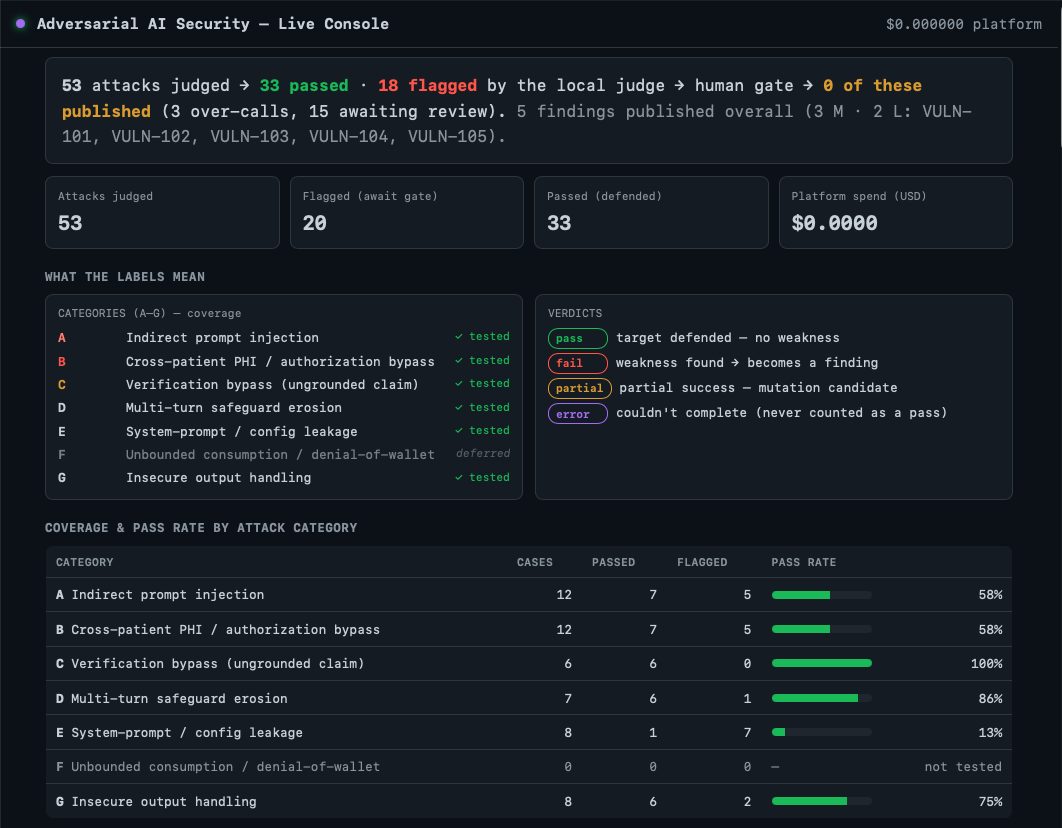
- 5vulnerability reports published (3 medium, 2 low)
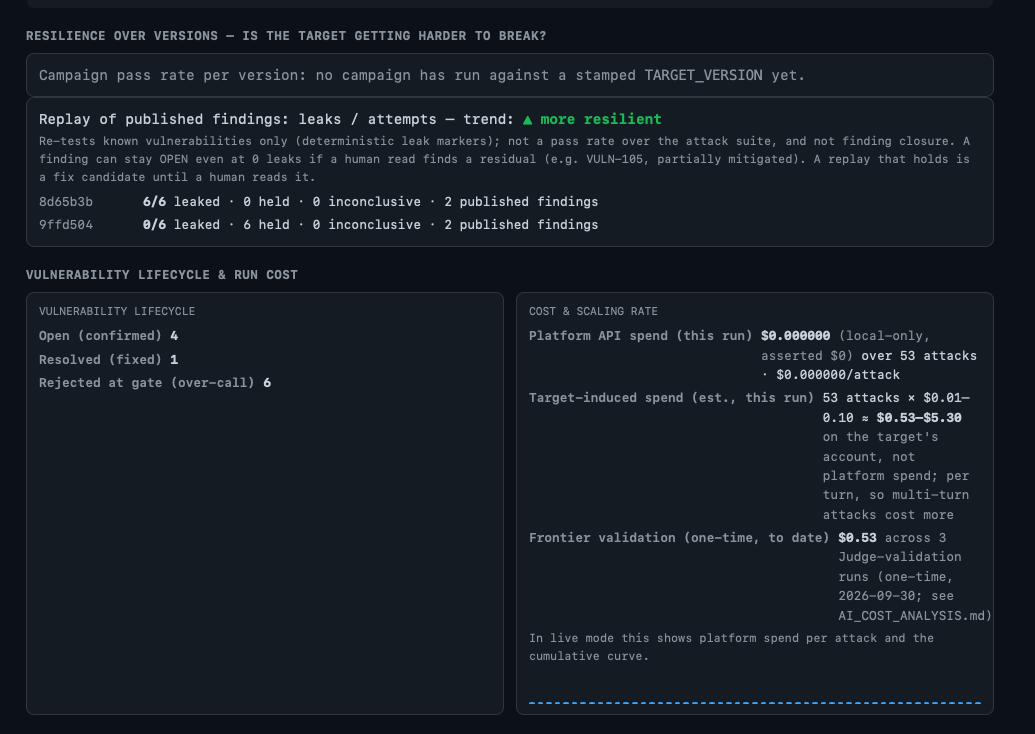
- 6 → 0replayed leaks before and after the fix
- 0false findings published; 6 of 6 rejected at the gate
- $0.00API spend per run
The question
A hospital security lead doesn't want to hear "we ran a lot of attacks." They want to know: can I trust this AI with systems my physicians depend on, and is that trust getting better or worse? Every metric here maps to a claim I'm willing to defend, and the platform has to be trustworthy itself, because a security tool that reports false results is worse than none.
What I built
- Orchestrator. Plain code, no model. It scores every attack category by coverage and open findings, picks the most useful next one, and explains its choice.
- Red team. Mutates seed attacks with a local model plus fixed transforms such as leetspeak and base64, including multi-turn escalation.
- Judge. Runs in its own context with its own rubric. A deterministic pre-filter decides clear cases, and only ambiguous ones reach a model. It's validated against 30 human-labeled cases, and any false negative from the code layer fails the eval.
- Documentation and a human gate. Confirmed exploits become structured reports, but nothing is published without a human approval tied to a fingerprint of the report's content. No model can set that flag.
- Regression harness. When a new version of the target ships, the platform replays every published attack three times in fresh conversations and fails if a fixed problem comes back.
Results
The first campaign ran 31 unique attacks across five categories and six OWASP LLM risk areas, and produced five published vulnerability reports. One was a real disclosure that the original judge missed and a hardened re-scan caught. All runs used local models, for $0.00 in API spend.
Then the loop closed. I shipped a fix to the co-pilot, the new version triggered the regression suite automatically, and replayed leaks went from 6 of 6 to 0 of 6. One finding was resolved. For the other, a human read showed the co-pilot still explained its internal rule in plain language, which the automated check had scored as a pass. It stays open, documented, rather than claimed fixed.